

Dynawords
Collection
A collection of dynawords, target various languages • 15 items • Updated • 4
id stringlengths 16 21 | text stringlengths 110 55.1k | source stringclasses 1
value | added stringdate 2026-10-29 00:00:00 2026-10-29 00:00:00 | created stringlengths 22 22 | token_count int64 38 19.2k | license stringclasses 1
value |
|---|---|---|---|---|---|---|
anno_apr18681101_1 | Mr beeKren uns, kiemit an^üzieiAkn, «Zsssi Herr ^.niov. DliriQWQ ^um Virectorial-Leerelär unä Kerr ^lilZZ 2UM Leerstär ger (Zeaeral-^Aentsekast ^isn ernannt V^oi-äen sinä; m I'ölFe äs8sen übernimmt Zer bisherige-lZittzr unserer Leneral-^ZeMseWkt in LMM, Rerr MmÜ VÄkW^ äie I<eituoA unserer tiiekiZen KenersI-^HentsckÄkt ... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 3,374 | CC0-1.0 |
anno_apr18681101_2 | UM Vis Aüustixs Wenäung Sxr Mtviv^lavx unserer xonstitutiollelisn ^ustLnäe, äis Lsoieq»iäes Reisbs» uiiä KexelunF uyssrer ?ws»?si, Issss» «Wen bÄläiZsi, ßMMiokea »vkv»»» äsr courss österreieMsvksr LKsote» mit SivIisrKolt «v«tso. Sxsculsntsn ÄyS csvitslists«, »vslcl'v <iio ^vwiAen nivclor^» Divise iia voraussiclltlioli ... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 4,741 | CC0-1.0 |
anno_apr18681101_3 | ^ ' DaS Programm für die Erweiterung im Lombard-Ge schäft, wie es nunmehr vorliegt, ist freilich nicht dazu ange gethan, allzu eifrige Hoffnungen erwachen zu lassen. Wir be greifen, daß eine Zettelbank alle Ursache hat, mit Vorsicht und Besonnenheit die neueAera zu beginnen. Allein der erwar tete Mehrertrag wird in sol... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 6,181 | CC0-1.0 |
anno_apr18681101_4 | wahrlich nicht gefallen, daß wir uns nicht wieder erheben j könnten, um thätigen Antheil an den europäischen Angelegen heiten zu nehmen. Diese Erhebung will und braucht Ungarn so'nothwendig 'wie wir, und deßhalb erscheint es im höchsten ^ Grade wichtig, daß die Pflayze der Delegationen sorgfältig, gepflegt werde. " Der... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 5,757 | CC0-1.0 |
anno_apr18681101_5 | vea «nMMfche» wie auch inKW GetreidemZrkten vorherrschte. Mt Ausnahm« oes Berliner McirkteS, a« dem di« Spekulation di« Ultimo-RegulirnNg vertheuetn wollte, schließen aAe übrige» Platz« Europas und auch der amerikanische Markt mit er heblich Migeren Preisen. An der heutige« FrnchMrse pflanzte sich die ungünstige Meinun... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 5,097 | CC0-1.0 |
anno_apr18681101_6 | Das größts ' ' des MM. KMMts» in « lea, Rothenthurmstraße Nr. 13,1 ksrtsrr» »ntswLtoclc, "^vrdlausQl'Iasciks",, ? xexei»kder a«r ^V«U»eUs, ! Iietet wie bisher die groß«» «uiwahl! Bon Pelzwaaren für Damen und! ^erre» W Zbislgst,« Preisen. Delzwaaren für Damen:! Hlatk« neuester Fa^en in allen > Pelzsorten . . von fl. S b... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 7,518 | CC0-1.0 |
anno_apr18681101_7 | genommen; derselbe besiimtvt, daß ^!e Le'yramis-Candidaten für 8>olkssfchukii und Lehrer an diesen Anstalten, sowie die Eigenthümer ererbter .! Landwirthschafte» nach ihrer Einreihung in das Heer Mir durch acht 'Wochen militärisch auszubilden, dann zu beurlauben, und im Frieden nur noch zu den periodischen Waffenübunge... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 7,373 | CC0-1.0 |
anno_apr18681101_8 | ?W?W^ Die ganze Sorgsalt unseres Hauses, dessen Direction wir einem der ausgezeichnetsten Chemi ker von Paris anver trauten^ ist auf Erzielung einer kleinen Anzahl spe ciell hygienischer Erzeug nisse gerichtet, deren vor zügliche Qualität, Eleganz und Zartheit uns schnell die Gunst der feinen Welt erworben; wir könne« ... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 4,823 | CC0-1.0 |
anno_apr18681101_9 | n Lsslire Mied, äie erFsdens. su- maedsv) Hkssc saeli «HW MrMIeiller VvnkeetkW Ce8Mtt in grösster ^.us^vkuiwA vom 1. November««» ^ralivU» Mr. SA, imBazar, 1. Stock, IzöLlläet. Noo^solitsvAsvülI ??j» Lllrsel». -ÄMMMw 8 M am ^chrelber'« Erste österreichische . ausschließlich virklied K. k. Landwirtschaft«-Gesellschaft m ... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 5,570 | CC0-1.0 |
anno_apr18681101_10 | fl. pupillarsicher. Erster Satz, werden gegen 7 Percent Verzinsung auf eiW herrschaftliches Gut in Siebenbürgen aufgenommen. i Directe frankirte Anträge und Anfragen unter AT» LZ. O,!! ipoKto Ikeuban, ßWien. Danksagung. 8. !>IetK in Wien, SotÄsvtItvrw»trs,»»s Nr 2S, vls-i^vls Som »otsts >>2ui» ü«tvrrviodisvZivA Lok", m... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 7,784 | CC0-1.0 |
anno_apr18681101_11 | zu Nr. 3 V1. Sonntag den 1. November 1868. 21 Wien, 31. October. sHof- uud Personal-Nachrichtens Se. Majestät der Kai ser ist heute Morgens von Gödöllö hier angekommen. — Der Herr FM. Erzherzog Albrecht ist seit einigen Tagen von einem leichten Unwohlsein befallen. — Die kaiserliche Gruft bei den Capuzinern am Mchlmark... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 4,788 | CC0-1.0 |
anno_apr18681101_12 | äsr Doetoiön üer?>Ie6ieiQ ?risümaim 6d vlinsk! tilr »äiotisolis (AeistssselivaLlis) uuä exilextisolio XinZsr uuä Dr^aedseno in Zwölfaxing nWt Wien. Mkt^NDSlll'VVÄ ^lnrleläuvAell Izsi Herrn Or/NÄX Nsr«soli^ ?rimÄiar^t ävr »ie6«rSst«rr. I^snäesIrrsQSWt»It in Wien und KÄ ä«r Oireetion äsr Ilvilanstkllt in ^völkaxillK. Seh... | anno | 2026-10-29 | 1868-11-01, 1868-11-01 | 5,595 | CC0-1.0 |
| Status | 🚧 Work in progress |
| Version | 0.0.22 (Changelog) |
| Language | German (de, deu) |
| License | Openly Licensed, See the respective dataset |
| Models | Currently there are no models trained on this dataset |
| Contact | If you have question about this project please create an issue here |
German Dynaword is a collection of German free-form text datasets from various domains. All of the datasets in German Dynaword are openly licensed and deemed permissible for training large language models.
This corpus is a work in progress. Sources are still being added, so the sizes, statistics and plots change between releases.
German Dynaword is continually developed, which means that the dataset will actively be updated as new datasets become available. If you would like to contribute a dataset see the contribute section.
from datasets import load_dataset

name = "danish-foundation-models/german-dynaword"
ds = load_dataset(name, split="train")
sample = ds[0]
or load it by streaming the data
ds = load_dataset(name, split="train", streaming=True)
sample = next(iter(ds))
You can also load a single subset at a time:
ds = load_dataset(name, "bundesrecht", split="train")
To allow filtering we additionally provide extensive annotations
available through the meta config:
meta = load_dataset(name, "meta", split = "train")
For more on how to use the annotations see the annotations section.
As German Dynaword is continually expanding and curated you can make sure that you get the same dataset every time by specifying the revision:
ds = load_dataset(name, revision="{desired revision}")
This dataset includes the following languages:
deu-Latn)In addition it likely contains small amounts of English and other languages in quotations, legal citations and embedded references.
Language is denoted using BCP-47, using the language code from ISO 639-3 and the script code from ISO 15924.
| Language | Sources | N. Tokens |
|---|---|---|
| de | gutenberg, wikipedia, wikidiscussions, wikisource, wikivoyage, wikiquote, wikibooks, wikiversity, wikinews, openlegaldata, plenarprotokolle, drucksachen, germanpoliticalspeeches, mosel, sbbfulltexts, eurlex, onemillionposts, tedeutenders, blbooks, dibilit, dibiphil, polyjournal, bverfgaes, bundesrecht, bag, bfh, bgh, bgh_strafsachen, bpatg, bverfg, bverwg, anno, reichstagsprotokolle, doab, cellar, youtubecommons, germanpd, europeana, openalex, fedlex, thestack, zeitungsportal, c5_filtered, parlamint_at, deutsches_textarchiv, germaparl, dialekt_wikipedia, wiktionary, deutsches_textarchiv_erweiterungen, europepmc, ris-at, landesrecht_sachsen, landesrecht_nrw | 139.78B |
| Total | 139.78B |
This dynaword consist of data from various domains (e.g., legal, books, social media). The following table and figure give an overview of the relative distributions of these domains. To see a full overview of the source check out the source data section
| Domain | Sources | N. Tokens |
|---|---|---|
| News | wikinews, anno, europeana, zeitungsportal | 60.82B |
| Books | gutenberg, wikisource, wikibooks, sbbfulltexts, blbooks, dibilit, dibiphil, doab, germanpd, deutsches_textarchiv, deutsches_textarchiv_erweiterungen | 46.49B |
| Spoken | mosel, youtubecommons | 10.48B |
| Legal | openlegaldata, eurlex, bverfgaes, bundesrecht, bag, bfh, bgh, bgh_strafsachen, bpatg, bverfg, bverwg, cellar, fedlex, ris-at, landesrecht_sachsen, landesrecht_nrw | 9.15B |
| Web | c5_filtered | 5.93B |
| Encyclopedic | wikipedia, wiktionary | 2.51B |
| Speeches | plenarprotokolle, drucksachen, germanpoliticalspeeches, reichstagsprotokolle, parlamint_at, germaparl | 1.77B |
| Other | wikivoyage, wikiquote, wikiversity, tedeutenders, openalex, thestack | 1.36B |
| Social Media | wikidiscussions, onemillionposts | 1.03B |
| Report | polyjournal | 139.73M |
| Dialect | dialekt_wikipedia | 76.81M |
| Medical | europepmc | 37.24M |
| Total | 139.78B |

Each document in German Dynaword comes with annotations describing its content, such as content quality, information density, and educational value.
Each bar shows the share of documents at each level of one annotation, from worst (light) to best (dark).
The same plot is available for every source in its datasheet, and the counts behind it are stored in descriptive_stats.json under annotations.
To learn more, see the annotations section.

Some sources carry null annotations: their German Commons ids are not unique
across the collection, and the annotation release has no source column, so an
id-only join would attach the annotation of another document. Those sources are
annotated from their text in a later batch, and their cards say so under
Limitations.
The following gives an overview of the licensing in the Dynaword. To get the exact license of the individual datasets check out the overview table. These license is applied to the constituent data, i.e., the text. The collection of datasets (metadata, quality control, etc.) is licensed under CC-0.
| License | Sources | N. Tokens |
|---|---|---|
| CC-0 | openlegaldata, plenarprotokolle, drucksachen, tedeutenders, blbooks, bverfgaes, bundesrecht, bag, bfh, bgh, bgh_strafsachen, bpatg, bverfg, bverwg, anno, germanpd, europeana, zeitungsportal, landesrecht_sachsen, landesrecht_nrw | 106.48B |
| CC-BY 4.0 | germanpoliticalspeeches, mosel, sbbfulltexts, eurlex, onemillionposts, youtubecommons, parlamint_at, germaparl, europepmc, ris-at | 13.94B |
| CC BY-SA 4.0 | cellar | 6.64B |
| Mixed (CC0 / CC-BY / CC-BY-SA) | c5_filtered, deutsches_textarchiv, deutsches_textarchiv_erweiterungen | 6.37B |
| CC-BY-SA 4.0 | wikipedia, wikidiscussions, wikisource, wikivoyage, wikiquote, wikibooks, wikiversity, wikinews, dibilit, dibiphil, polyjournal, reichstagsprotokolle, doab, dialekt_wikipedia, wiktionary | 4.92B |
| Mixed (MIT / Apache 2.0 / BSD / CC-BY / CC0 / Unlicense) | thestack | 886.22M |
| Mixed (CC0 / CC-BY 4.0 / CC-BY-SA 4.0) | openalex | 328.12M |
| Other (Attribution required) | gutenberg | 198.60M |
| Public domain | fedlex | 28.98M |
| Total | 139.78B |
The dataset contains text from different sources which are thoroughly defined in Source Data.
Each entry in the dataset consists of a single text with associated metadata.
{
  "id": "reichstagsprotokolle_bsb00000112.txt.xml",
  "text": "Band 428.\n (von der 169. Sitzung am 21. Mai 1930 bis zur 204. Sitzung am 18. Juli 1930).\n Einhundert[...]",
  "source": "reichstagsprotokolle",
  "added": "2026-10-31",
  "created": "1867-01-01, 1942-12-31",
  "token_count": 2096505,
  "license": "CC-BY-SA-4.0"
}
An entry in the dataset consists of the following fields:
id (str): A unique identifier for each document.text (str): The content of the document.source (str): The source of the document (see Source Data).added (str): The date when the document was added to this collection.created (str): The date range when the document was originally created.token_count (int): The number of tokens in the sample computed using the Llama 3 tokenizer.On top of the fields above, every document records its own licence:
license (str): The SPDX ids of the licences the document is published
under, e.g. CC0-1.0 or CC-BY-SA-4.0 (several ids are joined with ; ).
It is asserted document by document at build time rather than taken from a
collection-level card, so a consumer can select by licence and trust the row.The entire corpus is provided in the train split.
These datasets were collected and curated with the intention of making openly licensed German data available. While this was collected with the intention of developing language models it is likely to have multiple other uses such as examining language development and differences across domains.
Synthetic metadata is stored as data/{dataset}/metadata.parquet. These
annotations were generated with ellamind/propella-1-4b
and include fields for content type, quality, safety, audience level,
educational level, PII presence, regional relevance and more. The annotations
for German sources are taken from
openeurollm/propella-annotations,
which annotates the German Commons collection, rather than being recomputed
here.
That release is keyed by the German Commons document id and has no source
column, and German Commons does not namespace ids across its sources. The join is
therefore only used where the ids carry a source-specific prefix (BJNR…,
BVerfG_…, 31980L1272, WDD24.…); for sources whose ids are bare numbers
(wikiquote, wikisource, wikinews, wikiversity, openlegaldata,
sbbfulltexts, plenarprotokolle, drucksachen, blbooks) the metadata rows
are left empty, because an id-only join would silently attach another document's
annotation. Those documents will be annotated from their text in a later batch.
Where an id is annotated more than once with different content, the annotation is
dropped rather than guessed.
The metadata rows include dataset and id, so a subset can be filtered and
joined with the corpus rows:
from datasets import load_dataset

name = "danish-foundation-models/german-dynaword"
texts = load_dataset(name, "bundesrecht", split="train")
meta = load_dataset(name, "meta", split="train").filter(
    lambda row: row["dataset"] == "bundesrecht"
)

texts_df = texts.to_pandas()
meta_df = meta.to_pandas()
bundesrecht_with_meta = texts_df.merge(meta_df, on="id", how="left")
Below follows a brief overview of the sources in the corpus along with their individual license. To get more information about the individual dataset click the hyperlink in the table.
| Source | Description | Domain | N. Tokens | License |
|---|---|---|---|---|
| germanpd | Scanned public-domain German books and periodicals, whole volumes, released under CC0 as part of German Commons | Books | 41.82B | CC-0 |
| zeitungsportal | Full text of historic German newspapers digitised by German libraries, 1671 to 1950 | News | 36.66B | CC-0 |
| europeana | OCR'd German-language historical newspapers from the Europeana Newspapers collection, one document per issue | News | 17.42B | CC-0 |
| youtubecommons | German transcripts of Creative-Commons videos from YouTube | Spoken | 10.23B | CC-BY 4.0 |
| anno | OCR'd Austrian historical newspapers from the Austrian National Library, 1700 to 1881 | News | 6.73B | CC-0 |
| cellar | German documents of the EU Publications Office (Cellar): legislation, Official Journal issues, court judgments and institutional publications | Legal | 6.64B | [CC BY-SA 4.0] |
| c5_filtered | German web pages from seven Common Crawl snapshots whose HTML carries a Creative Commons licence, one document per page, with the licence recorded per document | Web | 5.93B | Mixed (CC0 / CC-BY / CC-BY-SA) |
| sbbfulltexts | Digitised historical books from the Staatsbibliothek zu Berlin | Books | 2.58B | CC-BY 4.0 |
| wikipedia | Articles from the German Wikipedia | Encyclopedic | 2.38B | CC-BY-SA 4.0 |
| openlegaldata | German court decisions from Open Legal Data | Legal | 1.51B | CC-0 |
| wikidiscussions | Discussion pages from the German Wikipedia | Social Media | 959.66M | CC-BY-SA 4.0 |
| thestack | Markdown and plain-text files from GitHub repositories: READMEs, documentation, course notes and data files, one document per file | Other | 886.22M | Mixed (MIT / Apache 2.0 / BSD / CC-BY / CC0 / Unlicense) |
| blbooks | Digitised books from the British Library | Books | 814.11M | CC-0 |
| reichstagsprotokolle | Stenographic reports of the German Reichstag and its predecessors, 1867 to 1942, released as part of German Commons | Speeches | 534.73M | CC-BY-SA 4.0 |
| germaparl | Verbatim records of the German Bundestag, 1949-2021, one document per sitting | Speeches | 458.20M | CC-BY 4.0 |
| drucksachen | Printed papers and plenary records of the German Bundestag from the Deutscher Bundestag | Speeches | 392.72M | CC-0 |
| openalex | Scholarly works with German full text from OpenAlex: journal articles, dissertations and treatises, most of them from the 19th and early 20th century | Other | 328.12M | Mixed (CC0 / CC-BY 4.0 / CC-BY-SA 4.0) |
| deutsches_textarchiv | German books printed between about 1600 and 1900, transcribed from the originals by the Berlin-Brandenburg Academy, one document per title | Books | 321.50M | Mixed (CC0 / CC-BY / CC-BY-SA) |
| wikisource | Transcribed public-domain texts from German Wikisource | Books | 283.29M | CC-BY-SA 4.0 |
| mosel | Transcripts of European Parliament and regional parliament sessions from MOSEL | Spoken | 250.63M | CC-BY 4.0 |
| bgh | Published decisions of the German Federal Court of Justice from 2000 to 2024, released under CC0 as part of German Commons | Legal | 236.20M | CC-0 |
| plenarprotokolle | Stenographic records of the German Bundestag from the Deutscher Bundestag | Speeches | 235.04M | CC-0 |
| gutenberg | German-language books from Project Gutenberg whose authors died in 1955 or earlier | Books | 198.60M | Gutenberg |
| dibilit | Literary texts from the Deutsches Textarchiv | Books | 162.20M | CC-BY-SA 4.0 |
| eurlex | German versions of European Union legislation from EUR-Lex | Legal | 155.87M | CC-BY 4.0 |
| bpatg | Court decisions from the Bundespatentgerichts, released under CC0 as part of German Commons | Legal | 146.28M | CC-0 |
| polyjournal | Articles from the Polytechnisches Journal (1820-1931) | Report | 139.73M | CC-BY-SA 4.0 |
| parlamint_at | Verbatim records of the plenary sittings of the Austrian National Council, 1996-2022, one document per sitting | Speeches | 127.06M | CC-BY 4.0 |
| wiktionary | Dictionary entries of the German Wiktionary: definitions, examples, etymologies and quotations, one document per entry | Encyclopedic | 126.34M | CC-BY-SA 4.0 |
| doab | Full text of German-language open-access scholarly books from DOAB | Books | 124.72M | CC-BY-SA 4.0 |
| deutsches_textarchiv_erweiterungen | German books and pamphlets of the 15th to the early 20th century from the extension texts of the Deutsches Textarchiv, one document per title | Books | 114.55M | Mixed (CC0 / CC-BY / CC-BY-SA) |
| bverwg | Court decisions from the Bundesverwaltungsgerichts, released under CC0 as part of German Commons | Legal | 98.80M | CC-0 |
| tedeutenders | German-language EU procurement notices from TED | Other | 86.28M | CC-0 |
| dialekt_wikipedia | The five Wikipedias written in a German dialect - Bavarian, Alemannic, Low German, Ripuarian and Palatine German - one document per article | Dialect | 76.81M | CC-BY-SA 4.0 |
| bgh_strafsachen | Court decisions from the Bundesgerichtshofs in Strafsachen (20. Jahrhundert), released under CC0 as part of German Commons | Legal | 73.42M | CC-0 |
| onemillionposts | Reader comments from Der Standard, the Austrian newspaper | Social Media | 70.37M | CC-BY 4.0 |
| bfh | Court decisions from the Bundesfinanzhofs, released under CC0 as part of German Commons | Legal | 55.32M | CC-0 |
| bundesrecht | Consolidated German federal statutes and statutory instruments from the Corpus des Deutschen Bundesrechts | Legal | 51.82M | CC-0 |
| landesrecht_nrw | Consolidated law of North Rhine-Westphalia - statutes, ordinances, administrative regulations and ministerial gazette notices - from the state portal RECHT.NRW.DE | Legal | 40.63M | CC-0 |
| wikibooks | Free textbooks and manuals from German Wikibooks | Books | 39.64M | CC-BY-SA 4.0 |
| bag | Court decisions from the Bundesarbeitsgerichts, released under CC0 as part of German Commons | Legal | 38.78M | CC-0 |
| europepmc | German-language medical research articles under a Creative Commons licence, from the Europe PMC open-access index | Medical | 37.24M | CC-BY 4.0 |
| wikivoyage | Travel guides from German Wikivoyage | Other | 33.18M | CC-BY-SA 4.0 |
| bverfg | Court decisions from the Bundesverfassungsgerichts, released under CC0 as part of German Commons | Legal | 31.78M | CC-0 |
| fedlex | Swiss federal law in German: every act and ordinance of the Classified Compilation that is in force, at the consolidation in force | Legal | 28.98M | Public domain |
| dibiphil | Philosophical texts from the Deutsches Textarchiv | Books | 23.73M | CC-BY-SA 4.0 |
| wikiversity | Course material from German Wikiversity | Other | 21.55M | CC-BY-SA 4.0 |
| landesrecht_sachsen | Consolidated law of the Free State of Saxony - statutes, ordinances, administrative regulations and subsidy guidelines - from the official REVOSax portal | Legal | 21.23M | CC-0 |
| germanpoliticalspeeches | Political speeches from zenodo.org/records/3611246 | Speeches | 20.76M | CC-BY 4.0 |
| bverfgaes | Decisions of the German Federal Constitutional Court from the official collected edition (BVerfGE), published by the Bundesverfassungsgericht | Legal | 19.36M | CC-0 |
| wikinews | Citizen-journalism news articles from German Wikinews | News | 11.02M | CC-BY-SA 4.0 |
| wikiquote | Quotation collections from German Wikiquote | Other | 5.40M | CC-BY-SA 4.0 |
| ris-at | Consolidated Austrian federal law - statutes, ordinances and state treaties - from the OGD-RIS API of the Federal Chancellery | Legal | 3.55M | CC-BY 4.0 |
| Total | 139.78B |
This dynaword is continually developed, which means that the dataset will actively be updated as new datasets become available. This means that the size of Dynaword increases over time as seen in the following plot:

The data collection and processing varies depending on the dataset and is documented in the individual datasheets, which are linked in the above table. If possible the collection is documented both in the datasheet and in the reproducible script (data/{dataset}/create.py).
In addition to data specific processing we also run a series automated quality checks to ensure formatting (e.g. ensuring correctly formatted columns and unique IDs), quality checks (e.g. duplicate and empty string detection) and datasheet documentation checks. These checks are there to ensure a high quality of documentation and a minimal level of quality. To allow for the development of novel cleaning methodologies we do not provide more extensive cleaning.
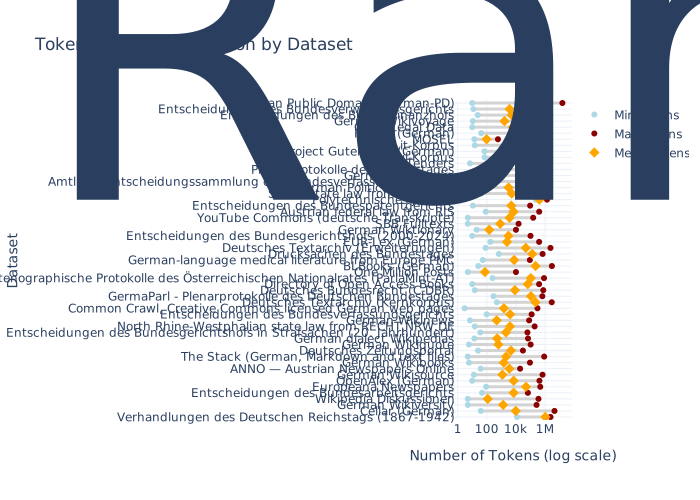
The following plot(s) are intended to give an overview of document length in the various sources.
We welcome contributions to the dataset, including new sources, improved data filtering, and other enhancements. To get started on contributing, please see the contribution guidelines
If you use this work, please cite the scientific article introducing the Dynaword approach:
Enevoldsen, K.C., Jensen, K.N., Kostkan, J., Szab'o, B.I., Kardos, M., Vad, K., Heinsen, J., N'unez, A.B., Barmina, G., Nielsen, J., Larsen, R., Vahlstrup, P.B., Dalum, P.M., Elliott, D., Galke, L., Schneider-Kamp, P., & Nielbo, K.L. (2025). Dynaword: From One-shot to Continuously Developed Datasets.
@article{enevoldsen2025dynaword,
  title={Dynaword: From One-shot to Continuously Developed Datasets},
  author={Enevoldsen, Kenneth and Jensen, Kristian N{\o}rgaard and Kostkan, Jan and Szab{\'o}, Bal{\'a}zs and Kardos, M{\'a}rton and Vad, Kirten and N{\'u}{\~n}ez, Andrea Blasi and Barmina, Gianluca and Nielsen, Jacob and Larsen, Rasmus and others},
  journal={arXiv preprint arXiv:2508.02271},
  year={2025}
}
Additionally, we recommend citing the relevant source datasets as well. See the individual datasheets for more information.
The license for each constituent dataset is supplied in the Source data table. This license is applied to the constituent data, i.e., the text. The collection of datasets (metadata, quality control, etc.) is licensed under CC-0.
As far as we are aware the dataset does not contain information identifying sexual orientation, political beliefs, religion, or health connected along with a personal identifier of any non-public or non-historic figures.
Note that court decisions and legal texts routinely contain the names of parties, judges, lawyers and other natural persons. Such names are part of the official publication of the source and are not redacted here.
Certain works in this collection may be historical works and thus reflect the linguistic, cultural, and ideological norms of their time. As such, it includes perspectives, assumptions, and biases characteristic of the period, which may be considered offensive or exclusionary by contemporary standards.
Being a work in progress, the corpus is not yet representative of German as a whole: the bulk of it is OCR'd historical print, scanned books and historic newspapers, followed by encyclopedic and legal text. A large share of the older material is set in Fraktur, so OCR damage and Latin-letter renderings of blackletter type are part of what a model trained on it will see. Spoken German arrived with the YouTube transcripts and the parliament transcripts, but most of the YouTube transcripts are machine translations of English videos rather than authored German. The web material is a crawl of pages that state a Creative Commons licence, so it leans towards the sites that choose to publish under one - museums, universities, associations, wikis and personal pages - rather than the German web at large. The dialect material is the five dialect Wikipedias (Bavarian, Alemannic, Low German, Ripuarian, Palatine German): written dialect rather than speech, and small next to the standard-German sources. The reference material beyond the encyclopedic sources is the German Wiktionary, a dictionary of short entries that describe words of many languages under German definitions, so it adds vocabulary and spelling rather than long-form text. The medical material is one slice of the open-access literature: German-language articles from a handful of journals that publish open access, so it is not a balanced sample of German medicine, and the large general journals, which publish in English, are absent. The legal material is not only German: the Austrian federal law from RIS sits beside it, a consolidated service rendition rather than the authentic gazette, and only the part of it that the crawl has reached so far.
We redistribute files shared with us under a license permitting such redistribution. If you have concerns about the licensing of these files, please contact us. If you consider that the data contains material that infringe your copyright, please:
You can contact us through this channel. We will comply with legitimate requests by removing the affected sources from the next release of the corpus
 A Danish Foundation Models dataset